MSI WS300 NVIDIA ConnectX-8 Performance
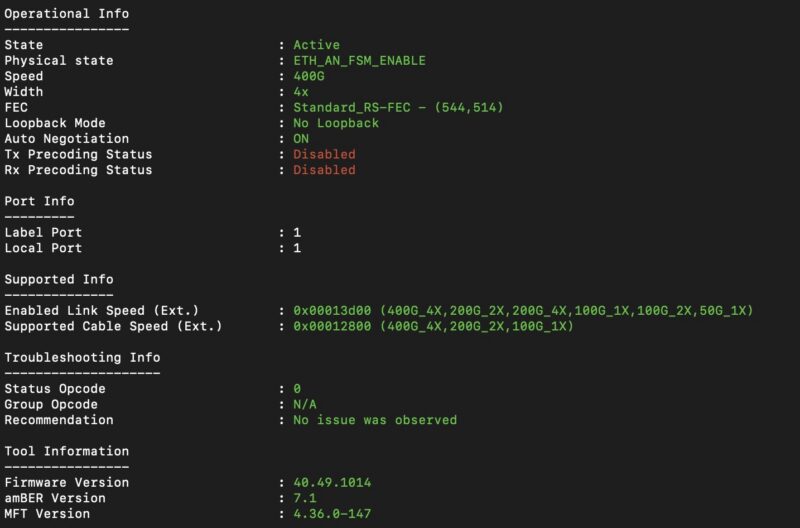
The NVIDIA DGX Station platforms use the same networking, so we were able to use this as another node to test between them. You will have seen this before, but we wanted to keep it in this review since it is a major subsystem and worth talking about in a bit of detail. We recently showed some of the optical modules we purchased for these machines, and why. The NVIDIA ConnectX-8 SuperNIC is a powerful networking solution with two 400Gbps rails, for 800Gbps of total networking capacity.
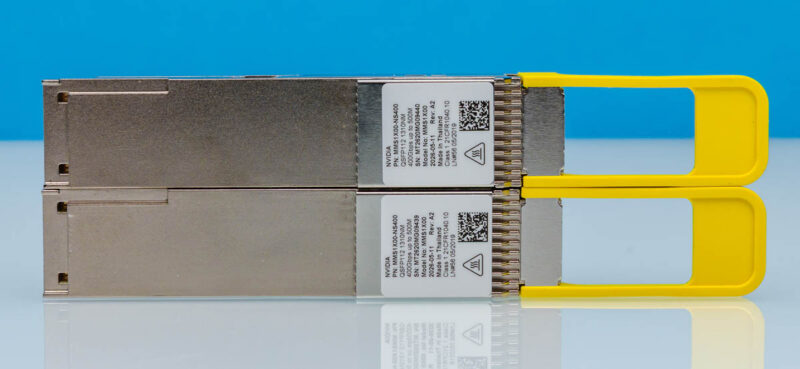
You can use DACs, like the massive NVIDIA 800G OSFP to 2x 400G QSFP112 passive splitter DAC, if you have a higher-end switch, but we wanted to see what would happen with a single 400Gbps link.
Here is a diagram of what we found. If you go back to the topology section, we found a PCIe Gen6 x16 link to the NVIDIA Blackwell Ultra GPU, which is why a dual-rail network can deliver 800Gbps over 2x 400Gbps links to the GPU.
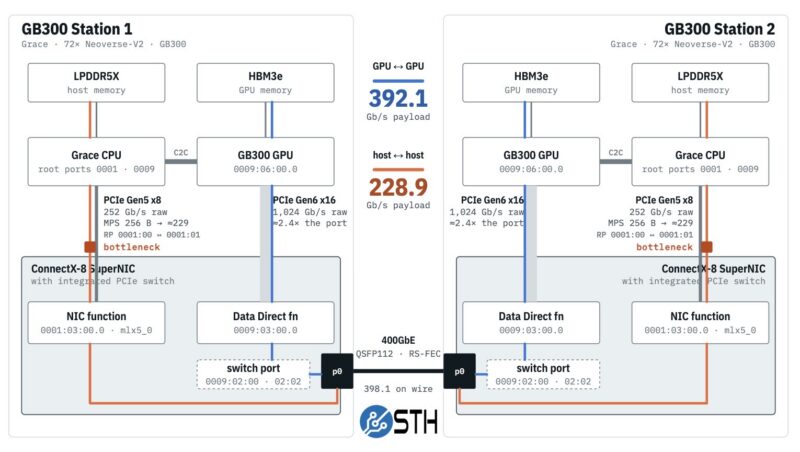
The host CPU side is very different. The PCIe Gen5 x8 link gives you up to around 229Gbps (we measured 228.9Gbps) to the NVIDIA Grace CPU side, which is limited by the Grace CPU’s PCIe interface to the ConnectX-8 SuperNIC. Remember, NVIDIA also has two PCIe Gen6 M.2 slots for eight more lanes off the ConnectX-8, so there is a lot going on here. Still, we had not seen folks discuss this before our first DGX Station review, and it is really interesting from an architecture standpoint. If you remember, we did a piece about how the NVIDIA GB10 ConnectX-7 200GbE Networking is Really Different. This is another case of NVIDIA doing something perhaps unexpected. The advantage is that NVIDIA uses the PCIe Gen6 switch on the SuperNIC instead of adding another chip that needs power and cooling in the topology.
Another neat thing was seeing 392-400Gbps of RDMA traffic over the link from the GPU. We originally saw around 1.4% CPU utilization on the system while doing that, and realized it was actually driven more by the polling we did to check performance on a single core. For some, that may seem like a given, but NVIDIA can only push 400Gbps, let alone 800Gbps for massive GPU scale-out bandwidth, with top-tier offloads.
For 800Gbps, we connected a second set of 400G DR4 optics and achieved 784.3Gbps of payload between the Blackwell Ultra GPUs, but still only 229.0Gbps between the Grace CPUs. Here is a diagram to help you understand the dual-rail architecture.
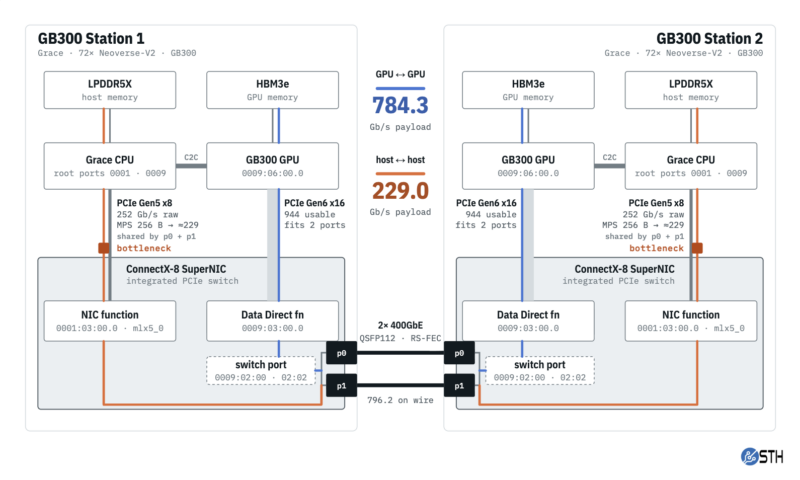
I think many will find the inclusion of NVIDIA Blackwell Ultra with HBM3E memory exciting. The Grace CPU is neat. What you should appreciate is that this system has the best networking you will find on a workstation today, since NVIDIA enabled a PCIe Gen6 x16 link between the Blackwell Ultra GPU and the ConnectX-8 SuperNIC, even on a PCIe Gen5 CPU. NVIDIA clearly architected this platform to scale out.
We also wanted to investigate another link: NVIDIA’s C2C link between the GPU and CPU.
MSI WS300 NVIDIA C2C Impact
This is another one that we showed previously. We tested it on three different DGX Stations to ensure consistent results. The MSI WS300 was usually spot on, with an average result and a +/- 2% variance. Again, you may have seen this before, but we thought it was worth sharing. NVIDIA touts its C2C link between the NVIDIA Grace CPU and the NVIDIA Blackwell Ultra GPU as a key selling point. We did a quick-and-dirty look at what happens not just with local LPDDR5X memory, but when the CPU accesses HBM remotely over the C2C link.
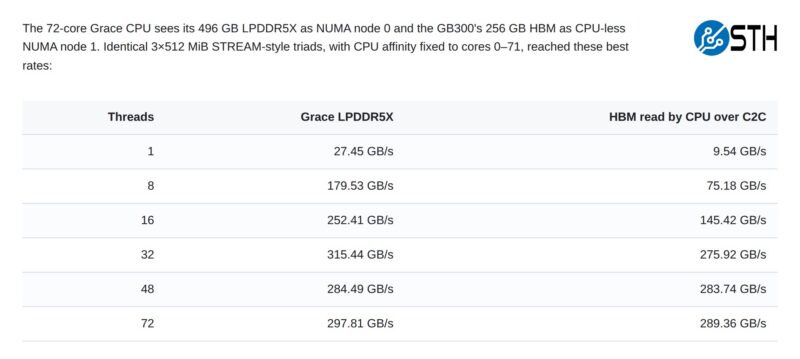
We started testing the possibilities. What if you wanted to run an LLM on the NVIDIA Grace CPU with LPDDR5X, not just on the Blackwell Ultra with its HBM? What would happen if you stored the model in the memory attached to the other compute and used the high-speed C2C link to transfer data?
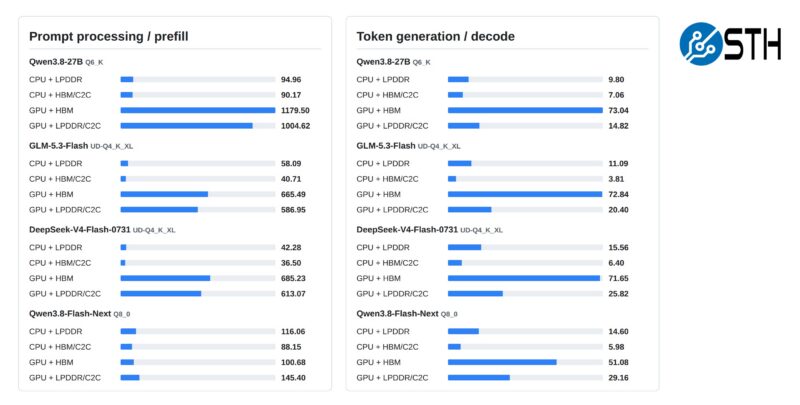
We ran Qwen3.8-27B, GLM-5.3-Flash, DeepSeek-V4-Flash-0731, and Qwen3.8-Flash-Next for coverage. Generally, the prefill worked well at passing data across the C2C link, which makes sense since that is more compute-bound than memory-bandwidth-bound. Still, using LPDDR5X over C2C to feed the GPU gave us better performance across the board than using the CPU with its locally attached LPDDR5X. Remember, a Grace CPU alone has more memory bandwidth than unified memory designs like the NVIDIA GB10 and AMD Strix Halo/Gorgon Halo. This is a great case for using LPDDR5X to expand memory capacity if you want to run a really large model, but it also shows why you clearly want to use HBM for decode.
Next, let us look at power consumption and noise.