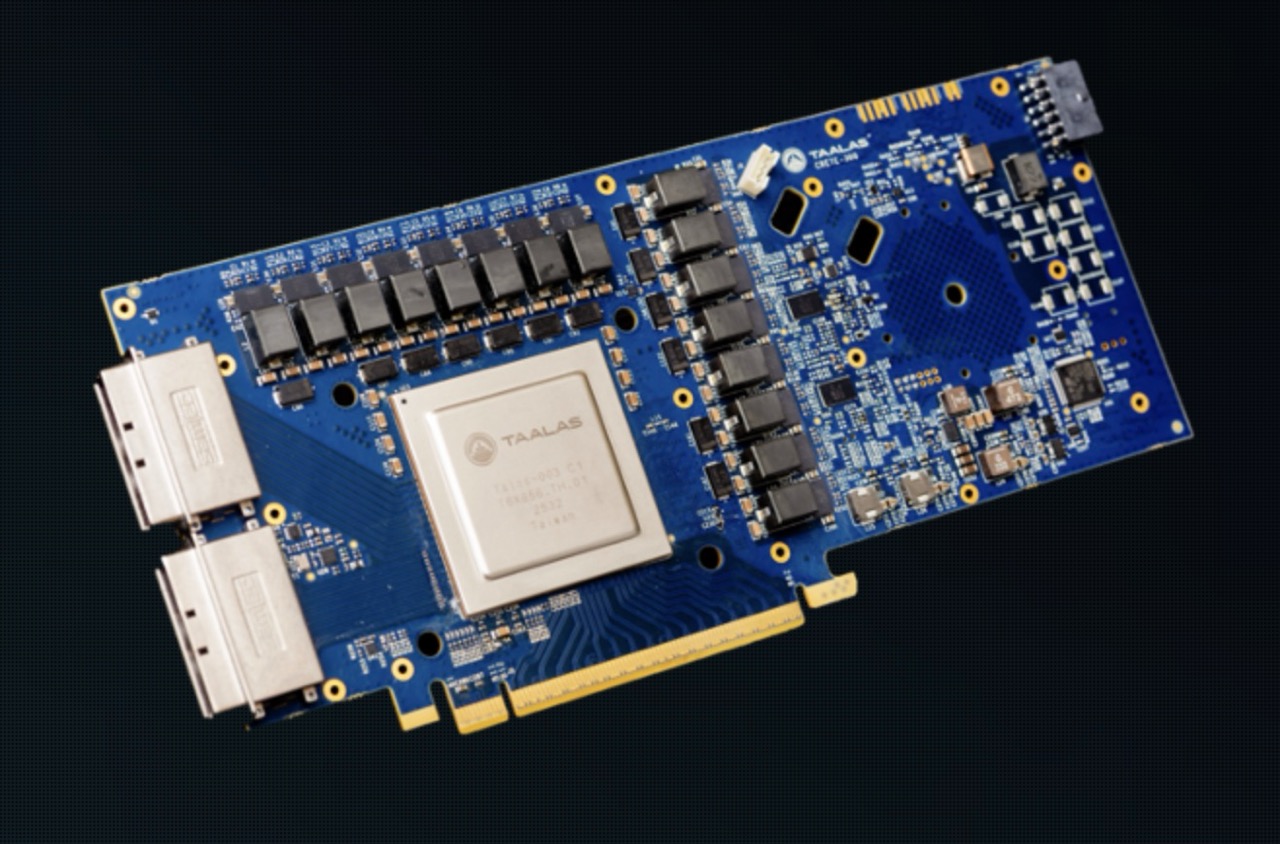
Today, AMD announced that it will acquire Taalas for a different kind of AI inference chip. Instead of having a highly programmable chip that can run many models and then using the programmability to change models, Taalas is the opposite. This is one chip, or more likely, one set of chips, per model. If you want to change the model being run in a rack, you also have to change the chips, since these are model-specific AI inference chips.
AMD to Acquire Taalas for Model-Specific AI Inference Chips
The basic concept behind Taalas is that instead of loading almost all model weights from memory like HBM, and then using the programmable portions of chips to handle a model’s specific matrix and compute needs, it just burns the model into CMOS. The benefit of this is that performance gains can be enormous compared to other solutions designed to be more programmable.
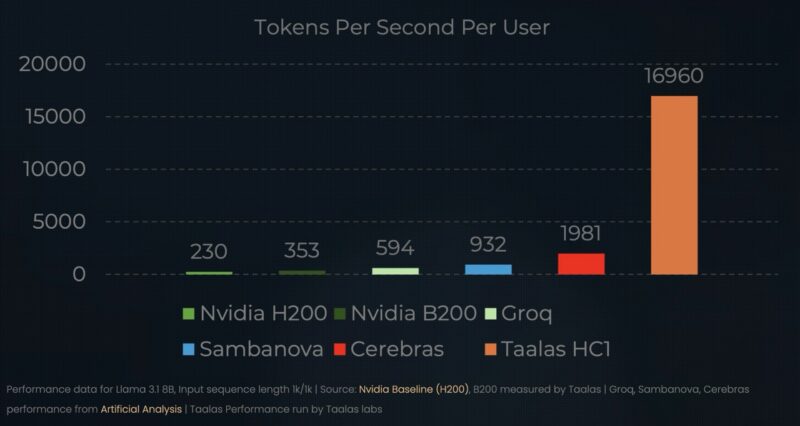
Taalas current-generation hardware is the HC1 technology demonstrator. The company showed the HC1 running Llama 3.1 8B and claims up to 17,000 tokens per second per user. Taalas lists the chip as TSMC 6nm with an 815 square millimeter die and 53 billion transistors. Taalas compares the HC1 against Nvidia H200 and B200, as well as Groq, SambaNova, and Cerebras, though those figures are Taalas’ own measurements.
Realistically, however, that means many larger modern models will require multiple reticle-size chips just to hold an entire model, especially a large one. Imagine having to fabricate ten, dozens, or even more different types of chips, package them, put them onto cards, test everything along the way, and then get software to tie all of the parts together. What if you need 10 different chips, and there is an issue with the 10th when it comes back, leaving you with 9 batches of chips waiting for that last one? While that sounds scary, this is a super-fast and allegedly lower-cost way to do inference.
Taalas says that changing weights, matrix dimensions, and other important bits only requires changing two mask layers. That means even if it needed many different chips per model, the number of expensive masks that would need to be produced is much lower than what would be used if you had to tape out two different GPUs, for example.
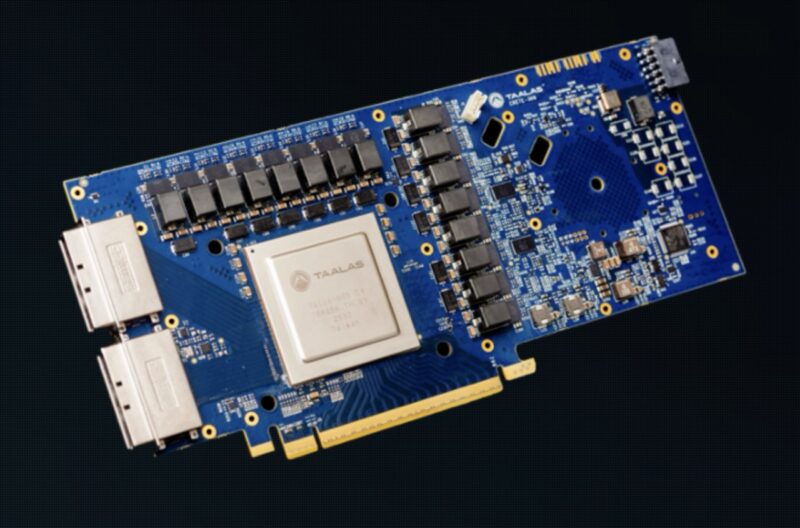
A model-specific chip trades flexibility for efficiency. Specialization can shrink the workload into a more direct dataflow, cutting the compute and memory overhead that general-purpose designs carry. In exchange, a rack built around one model cannot simply be re-targeted when that model changes. That makes this approach most attractive for stable, high-volume inference, which is the part of the AI market AMD says is growing fastest. Patrick also said: “It also helps when a model is rapidly adopted, workflows are built around it, and so a base load persists for some time, much like gpt-oss-20b/ 120b were widely adopted and still used today despite being well behind the leading-edge in their size categories. The longer model-specific chips can be used, the easier the business case is to accelerate the model with dedicated hardware.”
Final Words
AMD says it will fold Taalas’ technology into its accelerator roadmap and build system-level products around its Instinct accelerators. The move strengthens a full-stack AI platform that also spans Helios rackscale systems, EPYC CPUs, and ROCm software. Having an in-house model-specific inference engine gives AMD another option for customers who want maximum efficiency with a single stable model, alongside the general-purpose Instinct accelerators it already sells. The biggest open question is how quickly Taalas’ demonstrator turns into shipping parts, and whether single-model silicon can capture enough workload share to matter against the flexible accelerators the rest of the market ships. If nothing else, this is a big move for AMD.

How many users it can support – e.g. what’s the max tokens/sec if there are many users?
Putting the weights in a “3D AI V-cache” doesn’t seem so far fetched.
The cache carrying the weights likely has to be intimately connected with the processing elements to keep latency down. Not only would distant cache slow everything down, but a crossbar to allow the cache to service multiple processing elements would also slow everything down.
ChatJimmy is the service where you can try these out live. Coming from “llm on cpu” world where you measure seconds per token, this is like a different universe where you get whole reply in miliseconds.
They are doing an 8B model now. I would guess the next step is scaling up to 30B on a better node, maybe with 2 chiplets since they are already at the reticle limit for the first chip.
While the model is baked in, you can use LoRAs. The benefits are going to outweigh the limitations for some users.
The 8B model size restriction will quickly vanish with smaller nodes and especially packaging advances. TSMC already announced 14 reticles for 2028 and SoW-X with >40 reticles by 2029.
And I also assume that you can pack one single MoE expert on one chip, which reduces bandwidth requirements between chips.
Can someone explain the mechanics of why this is so much faster?
At the end of the day, its still transistors holding bit values. Whether that transistor is in memory or that transistor is on the board, what changes the performance so much?
Is it the work associated with the memory controller reading from scattered addresses vs the Taalas system being able to retrieve a model in one almost “coherent” dump?
Unless I’m missing something, you gotta wonder if some kind of FPGA + PROM setup (slow to write, but lightening to read) would be a better end goal.